On November 19 AWS published the logic and early evaluation behind Amazon Connect Talent’s structured voice interviews. The interviewer asks job-related questions and can follow up. A later process extracts behavioural evidence from transcripts and scores competencies against defined criteria. An industrial-organisational psychology firm commissioned by Amazon reviewed 36 interviews, identifying 252 rubric signals. AWS reports agreement with the reviewers on 89.3 percent of those judgements. The evidence makes the service worth a controlled examination. It measures how similarly software and experts coded parts of the same interviews. It does not tell an employer how accurately the tool will predict job performance, which applicants might struggle with its format or what happens when the scores are used to make real decisions. AWS’s interview evaluation
My procurement judgment is to evaluate this as a way to collect and organise evidence on a defined role. The business case depends on how well the questions serve that role, whether a human reviewer can make sense of a disputed score and how the employer responds when a candidate cannot reliably use the voice interface. A company that is unable to define a competency or provide a useful review procedure has work to do before the first interview is automated. The price of running an additional session is easy to find. The cost of an unfair rejection or an unreliable interview record has to be addressed by the hiring organisation.
November brought an evaluation, after the product had already launched#
AWS announced general availability on September 16, with the service then available in its US East Northern Virginia and US West Oregon regions. The November article explains the design and tests. It marks a move from showing what the product does to offering evidence about how it applies its chosen interview methods. The distinction is helpful to a buyer. A service can be available and still have unanswered questions about how to evaluate its performance. The case describes AWS’s current evidence for particular claims. It does not establish that a customer in each country, language or labour market has the same experience. A trial needs a specific region and recruiting workflow. AWS’s September availability announcement
This also matters when people hear the term structured interview. The underlying practice is much older than the software. Interviewers agree on job-relevant questions, seek comparable examples and apply a scoring guide rather than judging a whole conversation by impression. A 2022 meta-analysis by Sackett and colleagues discussed the validity of different selection methods. Structured interviews ranked highly in the revised comparisons, while the paper argued that prior estimates for many methods had been too high. That work gives employers a reason to care about structure. The next question is whether a particular implementation gives candidates a comparable way to demonstrate a job-related skill. The evidence about a general interviewing method cannot settle that product question on its own. Sackett and colleagues’ selection-method study
A structured process begins with what the job actually requires#
Connect Talent uses job descriptions and occupational frameworks to generate competencies, questions and a guide to what counts as evidence. Hiring teams can review and edit these before use. This is a useful design because it gives reviewers something concrete to inspect. The risk is that a poor job description becomes harder to notice after software makes it detailed and consistent. A question about customer handoffs might apply to one position and have little bearing on another. The employer needs someone who understands the job to explain what a proposed question reveals and where the answer will be used. A relevant, reviewable interview begins with that decision rather than with how long the system is available.
The commissioned review found that 91 percent of the generated competencies in its sample could be traced clearly to the job description, and 98 percent of questions targeted the intended competency. It also reports 94 percent of rubric signals measured the intended competency clearly. These are useful results for generated content prior to editing. They pertain to the jobs and materials reviewed and have their own units. They do not tell the employer whether its next job description is sound or what happens to the candidates when an inappropriate question enters the set. A hiring team can see the percentages as a reason to assess the mechanism and still require a person with relevant knowledge to approve the final questions.
There is another reason to compare questions to the job. A competency can be overly broad even when each question matches it. A position might need people to document a decision when information changes. An interviewer can look for an example of that specific action and let different backgrounds produce different good examples. A vague goal like sounding decisive can reward a manner of speaking instead. A precisely stated task helps reviewers determine whether a candidate showed an ability the job actually uses. It also gives an employer a defensible reason to change or remove a question that appears to become a proxy for something outside the role.
Separating a conversation from its score creates a useful review point#
AWS describes the conversation and assessment as separate. The interviewer gathers information and may ask follow-ups. The evaluation stage looks for a recorded behaviour, cites supporting transcript excerpts and calculates a competency score on a fixed scale from one to five. If there is insufficient evidence, the service flags the competency instead of supplying a score. This is a practical improvement over an isolated overall ranking with little explanation. A hiring team can check the passage and see whether the judgement follows. The important value is the ability to support a correction if needed. A credible human review has to reach the underlying evidence and have the authority to disagree.
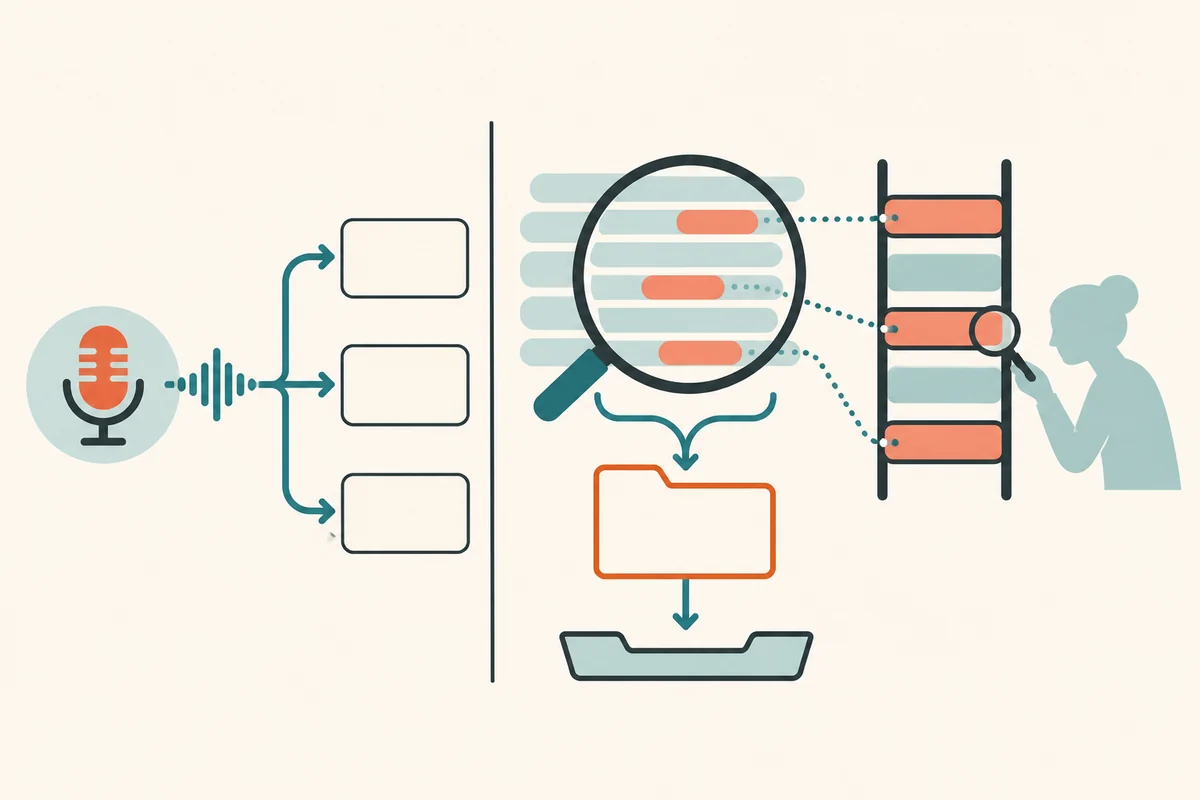
The missing-evidence flag is particularly important because important details can go unmentioned for many reasons. The question might have been unclear, a connection might have dropped, or a candidate might have described an example without explaining their own contribution. None of these states is identical to a candidate demonstrating that they cannot do the job. An employer should be able to distinguish an interview needing more evidence from a decision already made. Otherwise a downstream recruitment tool may turn an empty value into an adverse decision without anyone reading the transcript. An unresolved question needs a named owner and a path for getting an answer while keeping the candidate under consideration.
AWS’s preliminary comparison found that ratings based on initial answers alone were up to 1.14 points lower on a five-point scale than ratings using the full conversation. That is a reported maximum difference in this comparison, not a mean improvement that every candidate receives. It supports the plausible idea that useful prompts can bring forward missing context. The nature of those prompts matters. A follow-up might give someone a fair opportunity to explain a result. It might also vary in length, specificity and interpretation in ways that make two conversations hard to compare. The buyer needs to see how questions adapt across cases and whether both people had a fair chance to answer them.
Agreement is a valuable check with a narrow denominator#
The most quoted percentage is likely to be 89.3. AWS reports it for agreement with findings from an external firm evaluating signals across 36 interviews. It reports a higher 97.6 percent on the subset with clear evidence, and a Cohen’s kappa of 0.79. Kappa there accounts for expected agreement by chance. It is useful because two raters can agree frequently when most items fall into a common category. These data describe performance on the examples tested. They do not provide a hiring success rate. They do not establish a stable error rate for the next 1,000 applicants or for groups within them. The subset with clear evidence is helpful precisely because ambiguity can be where the harder review work lives.
It is also important to ask what happens when the assessors disagree. Did the source text support two plausible interpretations? Did the system miss a clear reference? Did a transcript omit part of the answer, or was the question itself unable to elicit the intended skill? A set of representative disagreements can be more helpful to a hiring team than another decimal place in the combined percentage. It allows managers to allocate time to steps where a person will genuinely change the decision. The buyer can also ask how the evidence set was chosen and whether the hiring team can evaluate the next group independently under an agreed definition of success.
The company also says structured scoring used all five points of the scale in its comparisons while holistic judging concentrated ratings in the middle. A wider distribution is useful only when it reflects meaningful variation. If two ratings differ, the reviewer needs to see how the answer and behavioural standard support that difference. Otherwise a score of two or four may look precise while sending a candidate into a different process for a weak reason. A better study would see whether well-explained score differences align with a job-relevant outcome and whether those differences persist for several recruiters, samples and periods of use.
Candidate access is an operating requirement that needs to be tested#
AWS says competency scores use transcribed responses and do not use video, tone, appearance or candidate identity information. Removing those inputs gives the buyer one specific design choice to verify. It leaves other questions about how the candidate gets to the transcript. A voice tool can fail to capture words, misunderstand a noisy exchange or ask an unexpected follow-up. Even a well-scored transcript can reflect a conversation that some people had difficulty completing. An employer needs to consider accessibility and alternative routes as part of the process, and assess how scores are used with those options available. A candidate should have a practical way to request help before their inability to use a particular format becomes an unexamined disadvantage. EEOC resources on AI and disability in hiring
A useful applicant experience makes the next step clear. A person should be able to understand that an automated interview is taking place, what information is collected and how to contact a person about a technical problem or an alternative format. The operator should have a way to explain which interview questions are being scored and to review an alleged transcript error. Those are product and process choices even when the vendor supplies a candidate portal. A manager can assign responsibility for following up clearly enough that the alternative does not quietly become a slower or less serious path. An employer can check those steps without claiming that a product page establishes compliance in every jurisdiction.
It is worth observing the stages before the score exists. An employer can measure invitations that go unanswered, incomplete sessions, requests for accommodations and follow-ups, using appropriate evidence and oversight. Candidates who finish are the only ones in a completed transcript comparison. People who could never use the expected setup may vanish from that denominator. Reviewing access patterns and the results of alternative methods gives the hiring team information about who its process actually reached. A claim of consistency should include both the fairness of the opportunity to answer and the quality of the judgement on the answers that were received.
Procurement has a calculable bill and less obvious costs#
AWS lists $20 for each completed evaluation combining its AI-led interview and candidate assessment. At the listed price, 1,000 completed paired evaluations would add up to $20,000 before the time of the people reviewing, operating and supporting them. The price page says the hiring organisation is not billed for a completion when an applicant does not finish. The candidate may still bear the costs of a failed appointment, and a recruiter may still need to intervene. A company should compare the full costs of reaching a usable, reviewed result with its current process. The published charge gives a clear unit for part of the analysis. It does not pay for the review it can create. AWS published pricing
Recordings, transcripts, assessments and applicant files are also part of the purchase. The AWS admin guide says transcripts, candidate assessment results and application materials default to deletion one year after creation and describes requesting different retention periods through support. A local hiring process may create additional copies when people export records or send an evaluation into another system. Those copies need their own handling. Procurement should make the retention responsibility explicit and identify who may view material at each stage. A team cannot infer what happened to all its records from the lifecycle of one set in one service. AWS’s retention documentation
The employer can also compare the technology with a smaller process change. An experienced recruiter might get better evidence if the organisation makes its questions consistent and gives time to compare disagreement. A voice service can give more candidates a wider set of scheduling options, which has real value where staff time is the constraint. Which investment is better depends on what hurts the recruiting process now. Paying to accelerate collection may help when reviewing is already reliable and resourced. If nobody has time to read the transcripts, a wider intake can give the same team more material to ignore. The budget should name which work is expected to move and which people will do the new work.
Give the next reviewer a decision they can reconstruct#
A candidate record may outlast the particular model, version and recruiter that produced it. When a reviewer looks back at an interview, they should be able to find the questions then in use, the evidence associated with the score and the person who acted on it. A display of the current rubric may be misleading if the criteria have changed. Enough context needs to travel with the evaluation to let the employer see which rule was applied and whether a person corrected it. That requirement matters even where the vendor improves its system over time. A better version today does not reveal why a candidate reached a particular outcome last month.
Changes to an interviewer or a rubric deserve an evaluation of their own. A buyer can ask how the provider describes a version change and what information remains available about earlier assessments. The employer can also decide when a change in job duties requires new questions. These are different reasons for reviewing the process, and they may require different people to approve it. One may be a verified improvement to the software, while the other changes the meaning of a skill for that employer. Without a clear record of both, it will be harder to compare results over time or to explain why an old decision cannot be reconstructed from the current interface.
An internal review can assign three concrete jobs. A role owner approves which behaviours the interview examines. A recruiting reviewer decides whether the evidence actually supports the score and records a disagreement when necessary. A service owner deals with access failures and can find the right person to provide an alternative. Those jobs can be done by the same person in a small organisation, but someone has to know they are responsible. The advantage of separating them is that a problem has a destination. Someone who reports an inaccurate passage should reach a reviewer who can verify and correct it, rather than be directed back to a screen that describes the score.
Compare what is saved with what moves to another part of the process#
An evaluation process can speed up an interview and still add work elsewhere. Recruiters may spend less time finding appointments and more time explaining unexpected results. A hiring manager may gain a fuller transcript but spend longer finding the sections that tell them what they need. Candidates may welcome a wider range of appointment times and object when no one answers a question about a broken session. A buyer can count these changes separately, so it can distinguish elapsed time from people’s time and from evidence quality. A vendor can create a larger number of completed sessions. Their value depends on how many of them become useful input to a responsible decision.
A better comparison includes the cases that are expensive precisely because something went wrong. There can be an interview that needs to be repeated, an interpretation that requires another person or an applicant who needs a different format. Preserving those cases in the pilot gives the sponsor information about support and any difference from current practice. A completed evaluation is a convenient pricing unit, but the business is paying for a route through recruitment with a clear outcome and responsible review. The trial should show whether the alternative changes that route in a way the employer can explain to both a hiring manager and a candidate.
A trial can test judgement before it influences hiring#
An employer can first ask reviewers to compare outputs on authorised cases without using the automated scores to make decisions. Agree on job-relevant criteria, which outcomes are unacceptable, and how disagreements will be reviewed. Use a comparable human assessment and give reviewers the full information they need. Include ambiguous answers, interrupted sessions and appropriate alternative formats, since those are where a voice-first system may cause the most friction. Track whether people can find the supporting evidence and identify places where the behaviour listed in the rubric is not demonstrated by the passage. That would show whether the tool improves the process without requiring applicants to rely on a new score while the company is still learning what it measures.
The exercise also needs a stop decision. An employer should be able to pause when access failures or unexplained discrepancies appear and designate who can revisit the record. It should know how the existing process continues if the vendor is unavailable. If the review is easier and the evidence remains useful across actual recruiting conditions, the company can look at a carefully limited live trial with the proper review. A sponsor should leave time to observe later outcomes and record when people disagreed with the software. Those records are part of adopting an interview procedure well. They can help the next team decide whether the gains in scheduling or consistency are worth the cost.
AWS’s new disclosure strengthens the case for structured conversation as a tool that can be examined. It gives a buyer a defined unit, some review evidence and operational documentation. The employer’s decision still resides in the use case. Every advancement or rejection should have someone responsible for the decision and a way to inspect evidence when an answer is incomplete or an applicant raises a problem. The product is worth testing if the hiring team is buying a better record of a defined interview. The evidence for giving the resulting numbers more authority would need to come from how the local process works and whom it serves.